KJM

KANG JUNG MIN (강정민) — Seoul · KR / EN / 中文

I find problems nobody's looking at. Then I use AI to prove they're real.

Problem-finder; AI is the execution layer. Producer-turned-researcher working across AI production, evaluation methodology, and shipped product.

175M+
cumulative views, short-form operations
platform-reported · 9 company-owned channels · 3,300+ videos adapted & published · AI not used — separate stack
min ρ 0.993
IRT rank stability, lowest cell mean over a 150-condition synthetic grid (biased missingness)
sole-authored arXiv preprint 2605.11205 · simple averaging collapses to ρ = 0.24 in the worst case
~1 month
100% AI music video → national broadcast
2-person unit · released via Warner Music Korea distribution (company channel) · SBS News, Mar 2025
Why hire — the objections, answered with receipts ↓

01–03Cases — one grammar

Three cases, one grammar: Problem → Diagnosis → Execution → Result → Proof. Every number carries its measurement method. The order is causal — the first case created the question the second one answers.

CASE 01Origin — productionNuanced evaluation

A 100% AI-generated music video, on national news.

100% AI-generated · ~1 month · SBS national broadcast

NewTech (㈜뉴텍) · Music & Entertainment, Paju · Assistant Producer · May 2023 – Oct 2025 · shipped Mar 2025

Problem
A music company with a limited filming budget still needed a music video. There was no AI team to hand it to — the unit that solved this didn't exist yet.
Diagnosis
A conventional shoot failed on both cost and calendar. The real question wasn't "can AI make video" — it was which tool survives which scene. Instead of committing to one vendor, I benchmarked generative tools scene by scene; five made the cut, each mapped to the scene types it won.
Execution
Proposed and built the company's first AI production unit (2 people). Selected and integrated 5 tools — Midjourney, Kling AI, MiniMax, Runway Gen-3 Alpha, Topaz — and ran cross-tool English prompt engineering, since each tool takes a different input grammar, into a single edit pipeline.
Result
100%
AI-generated
every frame
~1 mo
concept → delivery
2-person team
SBS
national broadcast
news coverage, Mar 2025

Released via Warner Music Korea distribution — the company's existing label channel, not a personal credit. My part was the pipeline.

Proof
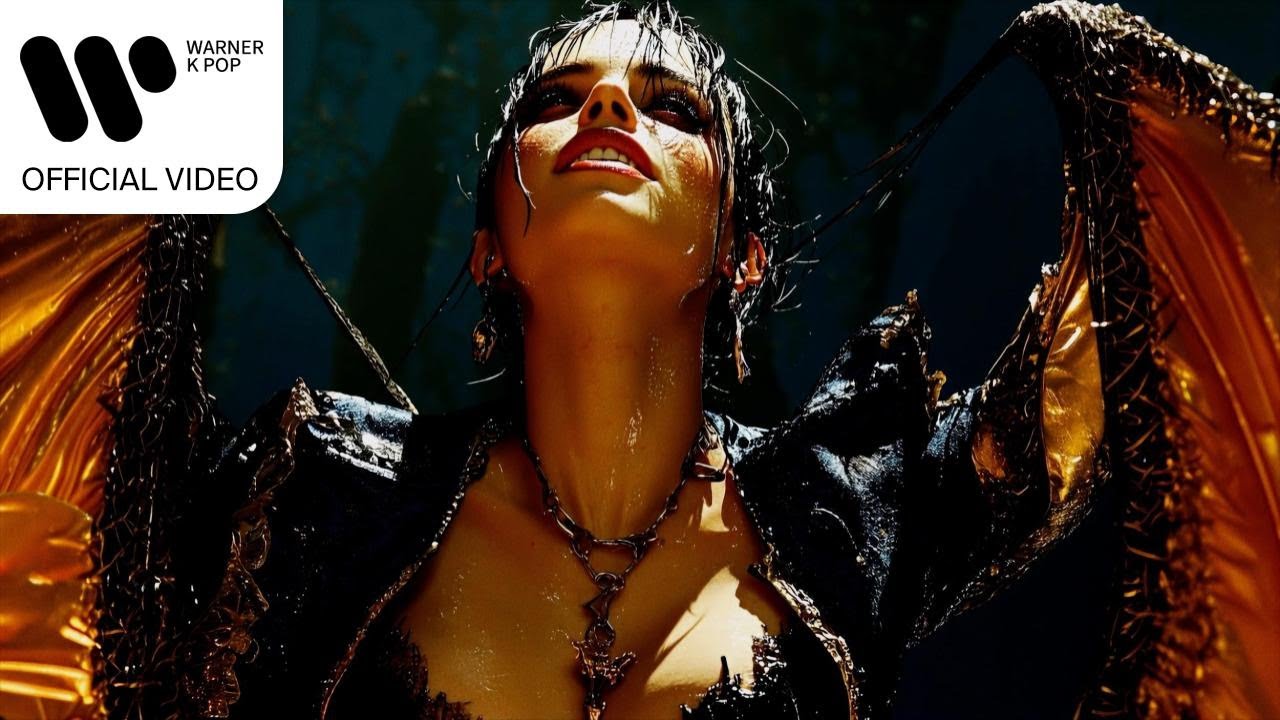
Still frame from AYOUNG — 'Waiting for the Sunshine', a 100% AI-generated music video

AYOUNG — 'Waiting for the Sunshine' · official YouTube embed, loads on click

CASE 02Method — researchEnterprise-grade reliability

The question became a paper: when does averaging lie?

Synthetic 150-condition grid, biased missingness: IRT cell means stay at ρ ≥ 0.993 (rounded) · simple averaging falls to ρ = 0.24

Independent Researcher · sole-authored · arXiv:2605.11205 · May 2026 – present

Problem
Every leaderboard averages scores. Under data sparsity and difficulty gaps, that average silently reorders the ranking — and the field treats it as ground truth. The tool-by-tool discrepancies I kept hitting in production were the same failure, one level down.
Diagnosis
Psychometrics solved this for human testing decades ago. Prior art applying IRT to LLM evaluation exists — my contribution is the systematic when and why: simulations calibrated to four domains (NLP, clinical trials, AV safety, cybersecurity), plus a separate 150-condition synthetic grid over sparsity × difficulty gap that maps where averaging fails and IRT holds.
Execution
Sole-authored, no affiliation, no GPU — IRT is a statistical model; the full 150-condition grid runs in about 80 seconds on an M1 Max laptop (NumPy/SciPy). arXiv endorsement secured by cold-emailing 5 professors; 1 replied.
Result
benign conditions high sparsity · difficulty gaps → ρ 1.0 ρ 0.24 IRT — min cell-mean ρ 0.993 simple averaging — ρ = 0.24 worst case

schematic of the headline result — exact curves and all 150 conditions in the paper, arXiv:2605.11205

Traction, measured against benchmarks: 5,184 LinkedIn impressions on the announcement — 23× the 225 median for sub-1K-follower accounts (MagicPost, 566K posts analyzed) — plus 17,000+ Threads views in week one. Playco Cofounder & Chief Product Officer Teddy Cross (Sequoia-backed $1B gaming unicorn) engaged with the paper directly on Discord — screenshot-verified.

CASE 03Application — productShipping daily value

7 live apps in 2 weeks. Day-30 retention reached 9.3%.

Day-1 37.0% · Day-30 9.3% · 7 apps / 2 weeks

Toss mini-apps · solo · AI-agent coding (Claude Code + Claude Design) · May 2026

Problem
Casual mini-apps are judged by whether users still return after Day 30. Most solo AI-built apps never get past toy status.
Diagnosis
With zero marketing budget, acquisition was the wrong lever. Retention design was the testable one: daily-streak and collection loops, engineered into all 7 apps from day one, then measured against public benchmarks.
Execution
Real React/TypeScript codebases — not no-code. AI-agent coding pipeline (Claude Code + Claude Design), solo, no server, no ads, no payments. Organic Toss traffic only.
Result
37.0%
Day-1 retention
마음동물 · Toss analytics
9.3%
Day-30 retention
마음동물 · ~2× the casual-game average
7 / 2wk
apps shipped, solo
code timestamps verifiable

User counts are small — organic in-platform traffic only, acquisition spend ₩0. The claim is the retention design, and it's framed that way on purpose.

Proof

04The hiring case

Hiring is a risk decision. This page's job is to make skipping the interview feel like the riskier option. So here are the objections a hiring manager should raise — answered with receipts.

Enterprise-grade reliability

AX Talent War 2026 / Samil PwC — Trusted CEO Agent Challenge

For a ₩30B decision scenario, I built a decision-boundary re-judgment agent where deterministic code owns every computation and judgment. The LLM only structures inputs and explains outputs, blocking hallucination by design.

Finalist · deterministic adjudication · human-readable rationale

"Will he wait to be assigned?"
The AI unit at NewTech didn't exist until I proposed it — nobody assigned the problem. The same pattern repeated twice since: the preprint and the 7 apps were both self-assigned, then shipped.
receipts: SBS broadcast · arXiv:2605.11205 · live apps
"Can he ship, or just start?"
Three shipped artifacts in 14 months, in three different formats: a music video on national broadcast (~1 month, 2-person team), a sole-authored arXiv preprint, and 7 live apps (2 weeks, solo). Different mediums, same finish rate.
speed record: ~1 mo · ~2 wk · independent research → public preprint · 14-mo window: Mar 2025 → May 2026
"No bachelor's degree."
Correct — so judge the evidence instead: a 960-hour IBM × Red Hat AX program (LLM/RAG workflows, watsonx, OpenShift, AWS EKS) and a preprint that cleared arXiv endorsement via cold outreach. Everything is public and checkable.
education record below · arXiv author metadata verifiable
"Are the numbers inflated?"
Every figure on this page carries its measurement method — "platform-reported", "company channel", "worst case". Honest negatives get published too: the cancer-data study reports its own weak rank-order result instead of hiding it.
method captions site-wide · honest negative: reverse-IRT / GDSC2 repo
"Cross-border team fit?"
Korean native · English fluent (raised in Ontario, Canada) · Mandarin conversational. Served as the company's first international representative at Edinburgh Fringe 2023 — artist interpretation and on-site logistics, in English, solo.
KR / EN / 中文 · operations record below

If any of these answers breaks in your context, that's the first thing I'd want to hear in an interview.

05Index — the ledger

Everything else, one line each. Same rule as above: a name, one number, a status, a source.

Research

EFSL — The Scaling Law of Evaluation Failuremin IRT cell-mean ρ 0.993 vs 0.24 averaging worst case (synthetic grid, biased missingness)preprintarXiv
Isomorph-Evalcaught a 41% error rate in my own variant pipeline pre-publishopen-sourcecode
AD-IRT — adaptive dimensionalityρ = 0.851, nested 5-fold CV on Evo-SOTA VLA dataopen-sourcecode
VLA scoring flaws — Evo-SOTA.io, 183 modelsIRT-based ranking for physical AI evaluationin preparationrepo
Reverse-IRT × cancer drug response (GDSC2)242,036 measurements · 82% cross-platform agreement · honest negative reportedopen-sourcecode
LLTM evaluationρ = 0.87 on unseen items at 50% training dataopen-sourcecode
PCR — psychometric content routing6.06 vs 3.67 / 10 (p = 0.004), zero GPU costopen-sourcecode
PCR2 — cold-start extensionρ = 0.963 recovered · 96.9% of oracle routing qualityopen-sourcecode
FIRE — Fisher information recommendation1.8× the catalog coverage of IRT on MovieLens-1M, explicit score decompositionopen-sourcecode
IRT × global financefund ranks shift up to ±30 positions · 50 ETFs, 217 monthsopen-sourcecode
IRT × cybersecurity (NVD)55,020 CVEs · up to 2.3× prioritization lift for mid-range vendorsopen-sourcecode

Build

My Celebfan-demand 1:1 video-call platform · 17 pre-launch featureslivesite
Salary Batteryincome → 30-day discharge-curve simulator, mobile-firstlivesite
SYNDImulti-model adversarial debate engine · 94 generated conceptslocal
NovelForgelongform fiction studio — chapter jobs, QC, EPUB/PDF exportlocal

Operations record

9 short-form channels (YouTube · Instagram)3,300+ videos adapted & published · 175M+ platform-reported views · peak Reel 19.2M · AI not used — separate stack2023–2025
Edinburgh Fringe Festival 2023company's first international representative · interpretation & on-site logistics2023

06About

My work started with a practical question on a production floor: why does the same input behave differently across tools, models, and benchmarks? Chasing that question turned a producer into a researcher — one measurement lens, applied wherever the same failure pattern shows up.

I build with AI as the execution layer: pipelines, a preprint, prototypes, products. The problems, the taste, and the finish rate are mine.

Education

IBM × Red Hat AX Academy960-hour intensive: LLM/RAG workflows, watsonx, OpenShift, AWS (EKS)2025.08 – 2026.02
Metalworks Institute — Mississauga, CanadaDiploma, Electronic Music Production · Ontario PCC Act 2005 · IRCC DLI O110123589171diploma

07Colophon — why this site looks the way it does

TypePretendard Variable — one family covers Korean and English, so a trilingual site speaks in one voice. Numbers are set in JetBrains Mono: measured figures should read like instrument output.
ColorPaper, ink, and one Fieldguide-green accent. The exact #22B573 signal is reserved for rules and dark surfaces; an accessible #0F7547 shade carries text on paper.
CaptionsEvery number carries its measurement method and source. Qualifiers are printed, not hidden — that's the whole research program, applied to myself.
MotionThe chrome stays still; only the work moves. The single animated graphic on this page is the paper's own result. Reduced-motion preferences are respected.
No 3D, no stockEvery visual here is an artifact of the work itself. Decoration without data would contradict the thesis.
EngineeringHand-written HTML/CSS/JS. No framework, no tracker, no build step — every claim is server-rendered text that humans, crawlers, and AI screeners can all read. Fonts are self-hosted.
Exhibit zeroThis page is itself the first work sample: a problem (be evaluated fairly in 90 seconds), a diagnosis, an execution, and a result you're reading now.

08Contact

Hiring for a role where problems need finding before they're assigned? Email me. I reply fast.